GPU compute from Python and JavaScript in the browser
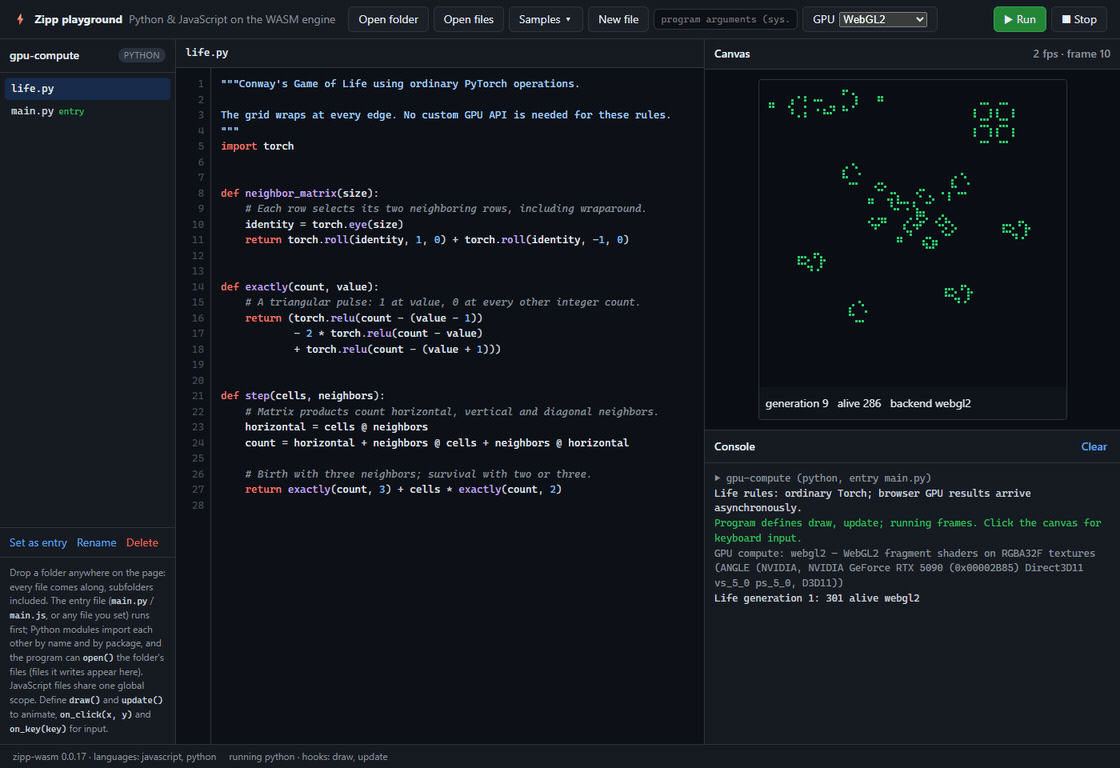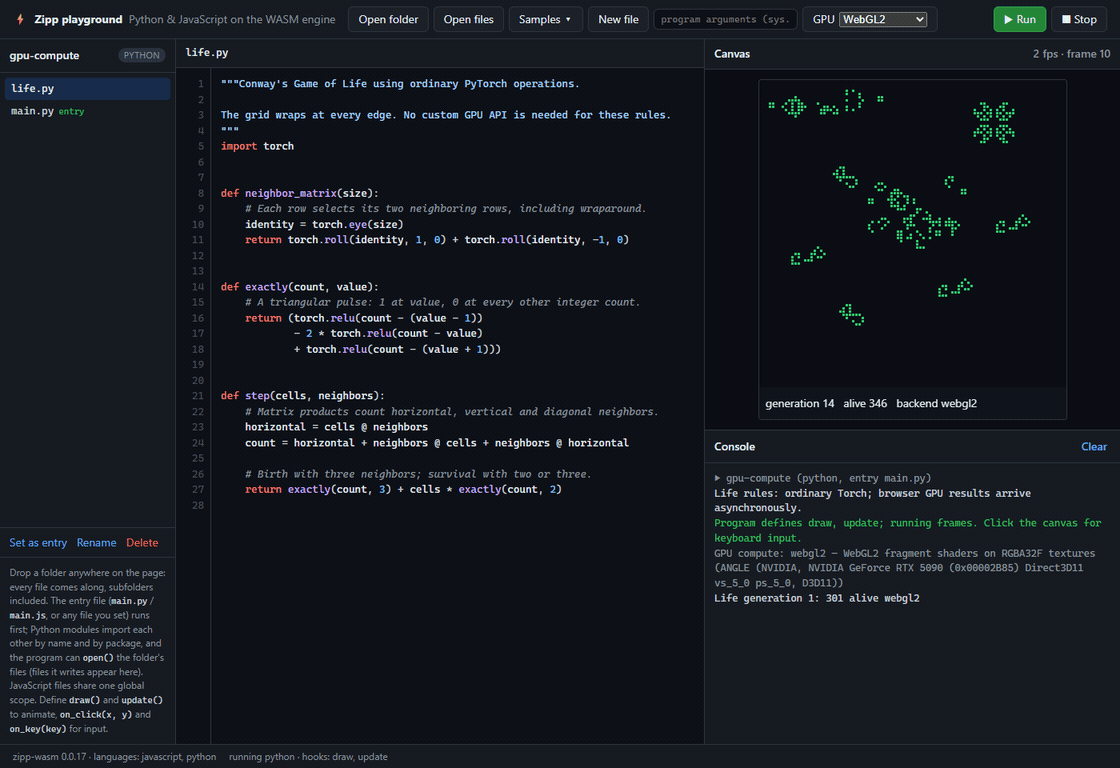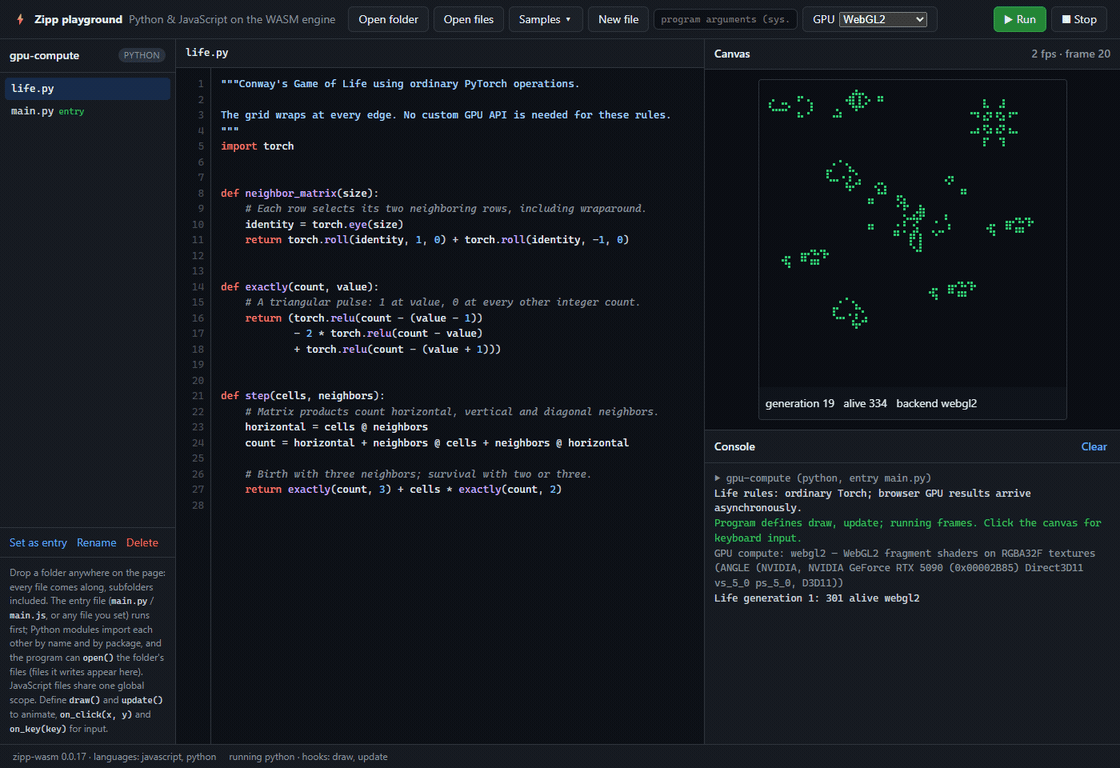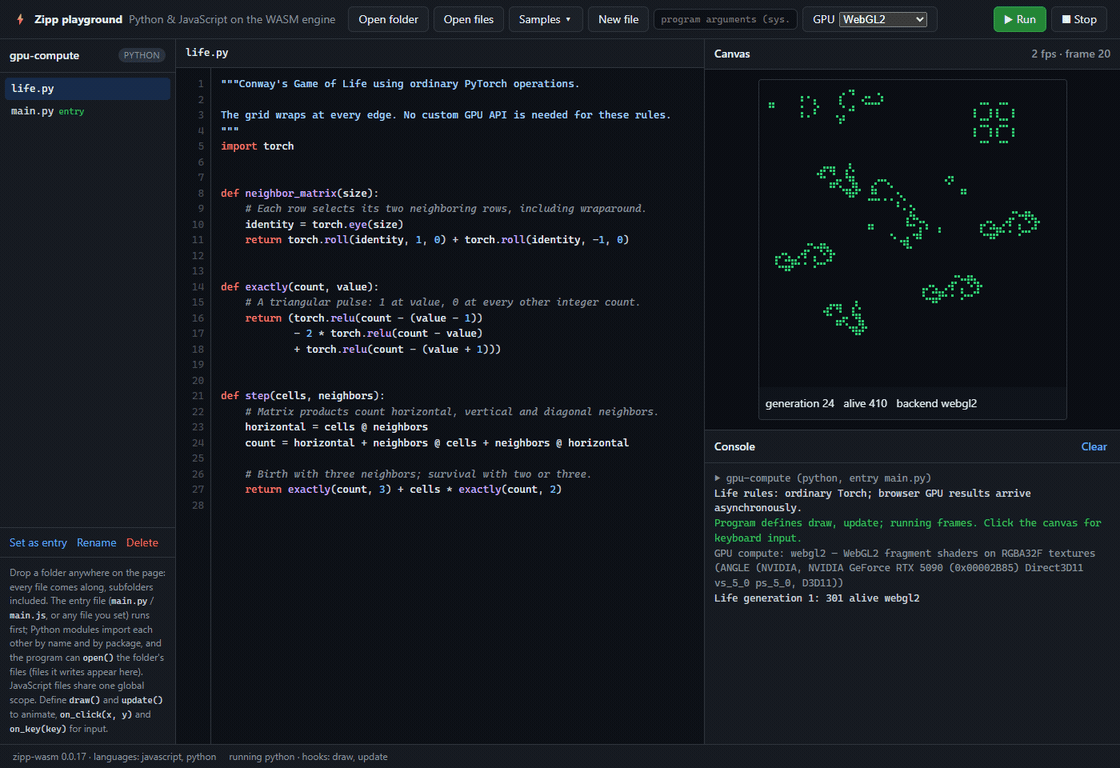
The GPU Lab is a bounded graph runtime: Python running on Zipp records a float32 graph, a host validates it and executes it on WebGPU or WebGL2 in the browser, or on a hardware GPU through wgpu natively, and the results come back to a Python callback. It is a working, limited, honest piece of infrastructure, and this page says exactly what it does and does not do.
What the GPU Lab is
A vendored JavaScript package, gpu-lab version 0.1.0, with four interchangeable backends: webgpu.mjs (WGSL compute shaders with a workgroup size of 64), webgl2.mjs (GLSL fragment shaders over float textures), wasm.mjs (no_std Rust kernels in kernels.wasm, which CI rebuilds to the same bytes) and cpu.mjs (a JavaScript reference). auto tries WebGPU, then WebGL2, then compiled WASM, then JavaScript, and records every fallback it attempted. Hardware paths reject recognized software renderers, because a missing GPU is not a successful GPU check.
Natively, zipp py runs the same graphs on a hardware GPU. The zipp-gpu crate runs gpu-lab's JavaScript runtime unchanged in a second, trusted Zipp state over a WebGPU API shim backed by wgpu (Vulkan, Direct3D 12 or Metal, loaded at run time), so the native GPU executes the browser's own WGSL kernels. It is synchronous like the CPU evaluator, so a program's output does not depend on whether a GPU is present; the adapter is probed on a program's first graph; a compiled call the GPU cannot run is re-evaluated on the CPU; and --no-gpu or ZIPP_GPU=0 keeps the CPU evaluator. Software adapters are not used. Float results agree with the browser's to about an ulp across shader compilers, and the exact operations (masks, dropout draws, slices, gathers, accumulation order) are bit for bit everywhere.
Operations and limits
Graphs are plain data (version: 1 or 2) over a fixed set of float32 operations. Version 1: input, full, scalar or shape-matched add, sub and mul, relu, positive masks, transpose, matmul, whole-tensor sum, and a toroidal Game of life step. Version 2 adds rank-4 NumPy broadcasting and div, neg, exp, log, sqrt, tanh, sigmoid, gelu (exact erf) and its gradient, permute and reshape, axis and whole-tensor sum and mean with keepdim, softmax and log_softmax, batched matmul, a fused cross_entropy with its gradient, and the sgd_update, momentum_update and adam update steps. Version 2 also takes a checkpoint's own q4_k and q6_k blocks as input data, decoded inside a transposed matmul, and matmul_fixed, a product accumulated in integers that gives the same bits on every backend that runs it. Version 3 adds maximum, minimum, comparison masks, where and a counter-hash uniform for dropout; version 4 adds strided slice, slice_scatter, index_select, gather and their gradients index_add and scatter_add, with the accumulation order fixed by the protocol. A graph is labelled with the lowest version it needs, so an older host refuses it rather than misreading it. The runtime does not turn arbitrary Python or JavaScript into shaders.
| Limit | Default |
|---|---|
| Nodes per graph | 512 |
| Elements per tensor | 4,194,304 |
| Summed logical node storage | 64 MiB, including every live session's resident tensors |
| Estimated operations | 100,000,000 |
| Named outputs | 64 |
| Sessions per runtime, steps per session run | 16, 64 |
| Live WebGL2 texture bytes | 128 MiB, counting RGBA32F padding (one scalar occupies a 16-byte texel) |
A prepared session validates and plans a graph once; input nodes without data are fed per step and may carry an output, so weights, momentum buffers and Adam moments never leave the device, and session.run(steps) executes one or many steps in a single submission with only the named outputs read back. For the 784-256-10 Adam step at batch 64 on an RTX 5090: 7.5 ms per execute() with everything read back, 3.6 ms per single-step run, 0.79 ms per step at eight steps per run on WebGPU (WebGL2 0.81 ms, WebAssembly 1.64 ms); five session steps equal five chained executes bit for bit on all four backends. A run that fails after device work began - a backend error, a non-finite readback, a failed map - poisons the session: run and download refuse with STATE and only dispose() remains.
Natively the same prepared sessions replay: after a session's first step the host records gpu-lab's command list and replays it, one submission and one readback per run, with batches written straight from Python's buffers. Large float matmuls use a register-blocked 128x128 tile where the device has 32 KB of workgroup memory (48 TFLOP/s on a 4096³ product), else 64x64; Direct3D 12 keeps smaller tiles because its compilers take minutes over the big one.
| Case | PyTorch CUDA eager | PyTorch CUDA graph | Zipp native prepared.step / 8 per run | Zipp in Chrome (WebGPU) / 8 per run |
|---|---|---|---|---|
| 784-256-10, batch 64, Adam | 0.78 | 0.17 | 0.27 / 0.12 | 2.9 / 0.65 |
| 784-1024-1024-10, batch 256 | 1.16 | 0.33 | 0.77 / 0.52 | 3.9 / 1.5 |
| 784-2048-2048-10, batch 1024 | 1.14 | 0.94 | 2.3 / 1.85 | 6.5 / 8.5 |
| 4096² matmul x4, inference | 10.3 (TF32 5.9) | – | 13.7 / 14.2 | 23 / 20 |
| Embedding 8192x128 + gather NLL | 1.14 | 0.30 | 0.36 / 0.24 | 2.7 / 0.40 |
A single step of the small and medium models and the embedding model is faster natively than PyTorch's eager CUDA, and at eight steps per run the small model beats its CUDA graph. Large products are still slower: this is float32 without tensor cores. Losses agree with PyTorch's within 1.4e-7 (small) and 3.1e-5 (medium).
From Python
from zipp_gpu import Graph

def show(result):
    print(result["backend"], result["outputs"]["values"]["data"])

g = Graph()
a = g.tensor([-2, 3, 4])
b = g.tensor([10, 20, 30])
g.submit(show, values=(a * b).relu())   # callback receives [0, 60, 120]
Graph.submit(callback, on_error=None, **outputs) records the graph as plain data and posts it as a host request; the callback receives a dict with backend, the named outputs (each with shape, dtype and a flat data list) and the host's stats. Tensors support broadcasting +, -, *, /, @ (batched too), .relu(), .gelu(), .sigmoid(), .tanh(), .exp(), .log(), .sqrt(), .softmax(), .log_softmax(), .sum() and .mean() over an axis or all, .permute(), .reshape(), .transpose(), .cross_entropy(), .positive() and .life(), and Graph offers sgd, momentum and adam update steps. Graph.prepare(feeds=, carry=, resident=, **outputs) returns a Session with run, run_steps, download and dispose, the same protocol as runtime.prepare above. The host adapter (createPythonGPUAdapter(engine, compute, { allowExecute: true, maxPending: 16 })) drains the request, validates, executes, and answers with pythonCall("__zipp_py_deliver", ...). Execution is granted explicitly, an explicit backend choice is never downgraded to CPU, and a late result never reaches a disposed engine. Run natively with zipp py, the same program runs on a hardware GPU through wgpu when one is present and on the CPU evaluator (cpu-python) otherwise, with the same output.
From JavaScript, without the VM
The runtime is also usable from plain browser JavaScript with no Zipp engine involved:
import { createRuntime } from "/gpu-lab/src/runtime.mjs"

const runtime = await createRuntime({ backend: "webgl2" })
const result = await runtime.execute({
  version: 1,
  nodes: [
    { id: 0, op: "input", shape: [3], data: [-2, 3, 4] },
    { id: 1, op: "input", shape: [3], data: [10, 20, 30] },
    { id: 2, op: "mul", a: 0, b: 1 },
    { id: 3, op: "relu", a: 2 },
  ],
  outputs: [{ name: "values", id: 3 }],
})
console.log(result.backend, result.outputs.values.data)   // "webgl2" [0, 60, 120]
runtime.dispose()
The playground currently wires zipp_gpu for Python guests only; a JavaScript-guest bridge exists for custom embedders but is not yet enabled in the stock playground.
torch.compile on the GPU
The Torch subset can route a model through the GPU Lab. torch.compile(model)(x) returns a pending result whose .submit(callback, on_error=None) delivers the tensor asynchronously; that method is a Zipp extension, because browser GPU completion is asynchronous and PyTorch's synchronous API cannot be reproduced. Supported inference ops are broadcasting add, sub, mul and div, relu, gelu, sigmoid, tanh, exp, log and neg, softmax and log_softmax over the last dimension, matmul, sum and mean over all elements or one dimension, transpose, permute and reshape, and the nn.Linear / activation / nn.Sequential combinations built from them. Protocol versions 3 and 4 add comparisons, where, masked_fill, clamping, maximum/minimum, dropout with a fresh mask every step, basic indexing, narrow/select/split/chunk/flip, cat/stack, index_select/gather and F.embedding, with PyTorch's gradients. An eager operation on a parameter inside the step is re-recorded on the parameter or refused by name, and CPU random draws inside a prepared step become per-step feeds, so a prepared session consumes the random stream exactly as the same eager steps do.
torch.compile(step, training=True) captures one training step: exactly one zero_grad(), a scalar loss.backward() and optimizer.step() with SGD (learning rate, momentum, dampening, Nesterov, weight decay, maximize and parameter groups), Adam or AdamW; optimizer state is read from optimizer.state, updated in the graph and written back. Higher-order gradients, RMSprop and amsgrad are rejected. Called directly, parameters are uploaded and read back on every call. compiled.prepare(x, target) records the step once from an example call and keeps weights, gradients and optimizer state resident on the device: step(callback, x, target) runs one step, steps(callback, batches) up to 64 in one submission, sync(callback) writes the state back into the model and optimizer.state, dispose() frees it; while a session is live, compiled calls and eager optimizer.step() on its parameters are refused. Ten model/loss/optimizer fixtures match PyTorch 2.11 to float32 rounding, and six more through prepared sessions after sync(). On an RTX 5090 in Chrome the 784-256-10 batch-64 Adam step costs 74 ms per compiled call, 5.1 ms per prepared.step and 1.8 ms per step at eight steps per run on WebGPU (WebGL2 89 / 3.3 / 2.2 ms, WebAssembly 74 / 4.9 / 3.6 ms).